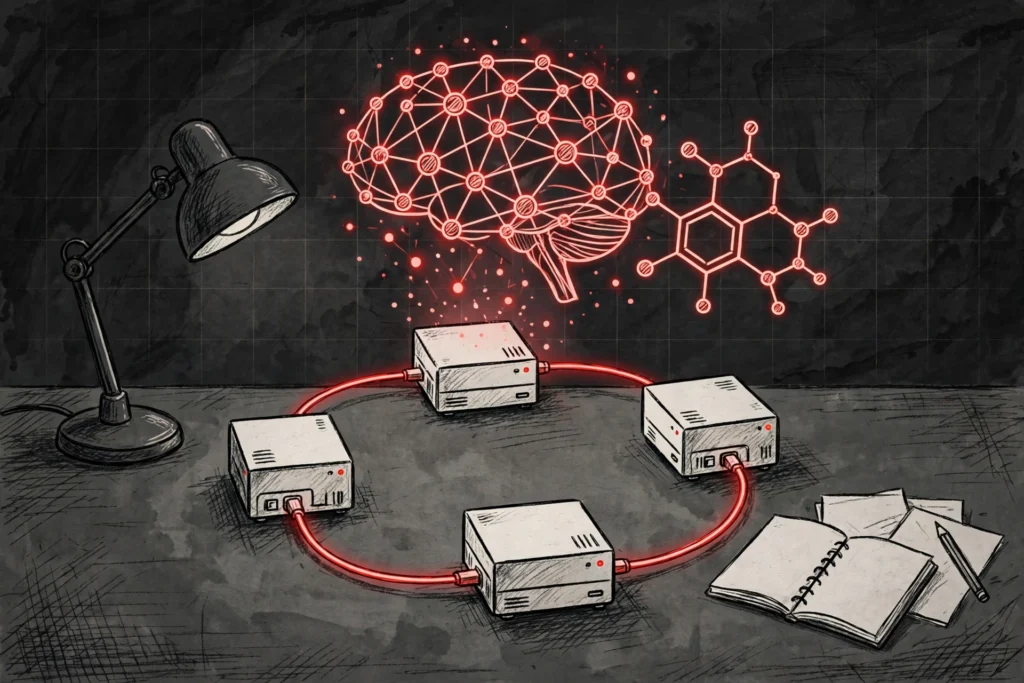
Picture a young researcher at a university lab, staring at a job scheduler at 2 a.m. Her simulation has sat in a shared supercomputer queue for eleven hours — and NVIDIA’s new DGX Spark HPC Developer Kit, announced November 16, is built to end waits like hers.
She has a deadline in the morning, a dataset she cannot legally move off campus, and a model she needs to test before anyone else sees the results. For decades, this was simply how science worked: if you wanted serious computing power, you waited your turn.
According to the company’s blog, the kit puts a four-node supercomputing cluster on a researcher’s desk, no data-centre badge required.
It was unveiled at SC26, the annual supercomputing conference taking place this week in Chicago. The idea is simple to state and hard to build: take four of NVIDIA’s compact DGX Spark desktop systems, link them together, and let a small team run the multi-node workloads that used to demand a room full of racks.
What the DGX Spark HPC Developer Kit Actually Is
Each node in the kit is a DGX Spark system, built around NVIDIA’s GB10 Grace Blackwell Superchip. That chip pairs a 20-core Arm processor with a Blackwell graphics processor, and both share a single pool of 128GB of unified memory.
One box on its own is already a serious machine for local AI work. The kit scales from one system to four. Link all four together and the numbers add up fast: 512GB of combined memory and 20TB of NVMe storage, according to NVIDIA.
The four systems connect directly to their two neighbours in a ring, using NVIDIA’s ConnectX-7 networking. There is no network switch to buy, configure or maintain, which is exactly the kind of detail that matters to a lab with no dedicated IT staff.
That memory is the real story here. A single DGX Spark can run models of up to around 200 billion parameters. Spread the work across four, and NVIDIA says researchers can deploy models with up to 700 billion parameters locally, using the compact NVFP4 number format.
The company names DeepSeek V4.1 as an example of a model in that class.
Four Boxes, No Switch, One Cluster
The ring layout is the clever part of the design. In a conventional cluster, every machine talks through a central switch, and that switch becomes one more thing to purchase, power and troubleshoot. Here, each DGX Spark plugs straight into its two neighbours.
The result is a cluster that a researcher can assemble on a desk and take apart again without calling anyone. Teams can develop and debug code on the four-node setup, watching how computation and data spread across the machines, and only then move the finished job to a full-size supercomputer.
The expensive shared resource gets used for production runs, not for trial and error. There is a second, quieter benefit too: work that never leaves the building keeps unpublished results and proprietary datasets on premises.
For a lab handling sensitive genomic data, a company’s unreleased designs, or a hospital’s patient records, that is not a convenience. It is the whole point.
What 512GB of Memory Actually Buys You
Big numbers on a spec sheet only matter if they change what a scientist can do before lunch. NVIDIA’s announcement leans on examples rather than benchmarks, and the examples are telling.
The demonstrated four-system workloads include LAMMPS with Kokkos for materials simulation and NAMD for molecular dynamics.
The wider DGX Spark community has already validated GROMACS for molecular dynamics, OpenFOAM for fluid dynamics and WRF for weather modelling on the hardware. On the AI side, the kit also runs NVIDIA NIM microservices such as OpenFold3 and Boltz-2, which predict the shapes of proteins and other biomolecules.
Fresh open datasets and post-training recipes for the Nemotron 3.5 Super VL model help researchers adapt that model for life sciences and chemistry work, without sending anything to the cloud.
Real Labs Are Already Using It
NVIDIA’s blog points to several groups already running real work on single DGX Spark systems, and their stories explain the appeal better than any specification table.
At the University of California, Berkeley, the Rubin Lab uses a DGX Spark and NVIDIA’s Evo 2 model to predict bacterial traits directly from genome sequences. Without the eleven-hour cluster queue times it used to face, the lab says results arrived fifteen times sooner.
Also at Berkeley, the Hartwig Group performs LoRA fine-tuning on the 120-billion-parameter Nemotron 3 Super model for chemistry machine learning. Running locally with NVFP4 quantisation, the group fitted a 120-billion-class model on a single device and strung together continuous eight- to twenty-four-hour training runs.
Elsewhere, the quantum-computing startup Kvantify reports running tensor-network simulations of quantum-chemistry circuits with up to 70 qubits and 975 gates on one DGX Spark. CYRAN AI, a spin-out from IIT Delhi, uses the machine to speed up JPEG 2000 decoding for large satellite images.
And the OpenFold team has shown how researchers can fine-tune OpenFold3 on a DGX Spark to improve protein-ligand structure predictions for drug discovery.
The Software Is Still Catching Up
For all the hardware’s promise, one piece is missing. NVIDIA says an installation playbook for its HPC SDK — the software development kit for scientific computing — is coming soon, but it is not available yet.
That playbook will bring GPU-accelerated C, C++ and Fortran compilers, libraries and message-passing tools to the cluster: the same development tools used on NVIDIA-powered supercomputers. Until it arrives, the kit is best understood as a developer platform rather than a finished product.
Researchers can already run AI models, agents and several validated simulation packages on it, but the full scientific-computing toolchain is still on its way.
What It Costs — and Who Should Wait
NVIDIA has not announced a price for the full four-node kit. The DGX Spark systems and the cables that link them are sold through NVIDIA Marketplace and a long list of partners, including Acer, ASUS, Dell Technologies, GIGABYTE, H3C, HP, Lenovo, MSI and xFusion.
Buyers will need to check with a partner for current pricing. For context, a single DGX Spark launched at $3,999 in October 2025, and prices have climbed since then as memory costs rose. A four-node setup is a serious purchase for a small lab.
Huge models fit, but they do not run fast. The kit is a development and prototyping machine, not a replacement for a data centre. Its value is in the iteration: test locally, debug locally, then scale the finished job to the big iron.
Why This Launch Matters Beyond One Product
The DGX Spark HPC Developer Kit lands at a moment when the computing world is splitting in two directions at once. On one side, the largest AI models keep getting bigger and more centralised, running in warehouse-scale data centres.
On the other, researchers, startups and small labs want to keep more of their work in their own hands. NVIDIA is selling to both sides. The same company that supplies the chips for the biggest supercomputers is now packaging a miniature version of that infrastructure for a desk.
If the bet pays off, the next generation of scientific software will be written and tested on machines like this one, long before it ever touches a supercomputer queue.
The kit arrives in the same season as a wave of open-weight models — DeepSeek V4.1 among them — that are large enough to need this kind of hardware and open enough to run anywhere.
What Happens Next
The developer kit is on display at SC26 in Chicago this week and is available for sale now through NVIDIA’s partners and its Marketplace. The HPC SDK playbook is the next milestone to watch.
Once it lands, scientists will be able to build and test multi-node GPU applications, explore mixed-precision algorithms and run molecular dynamics and materials simulations on the desk cluster before scaling up.
For the researcher staring at that 2 a.m. queue, the change is not that supercomputers are going away. It is that the queue is no longer the only option.
That, more than any specification, is what NVIDIA is selling: the ability to fail fast, iterate locally, and save the big machines for the runs that actually deserve them.


